Quantized space SVM
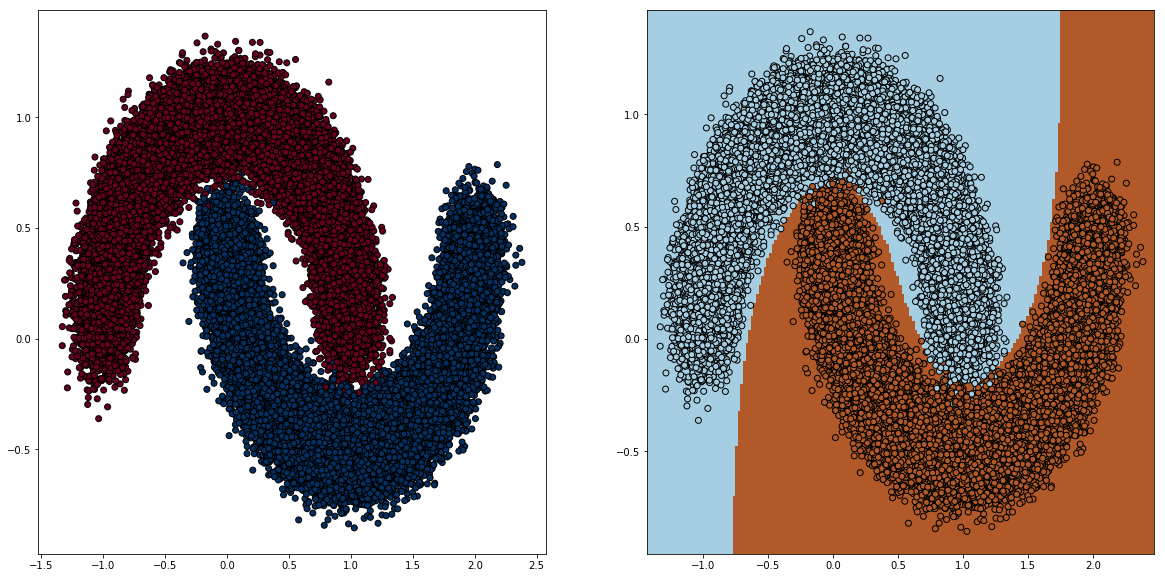
The original SVM calculates n^2 pairwise distances between datapoints, and in the case of Kernel SVM, it’s n^2 pairwise kernel distances. Memory consumption is also O(n^2).
It would give you a headache.
This notebook demonstrates the use of Feature Binning as a way to uniformly subsample the dataset, applied to kernel SVM.
The general idea is to put samples into buckets (bins), and use the bucket or the bucket average as the representative value for all of the samples in that bucket. The number of points that fall into each bin can be used as sample weights, if the ML implementation supports it.
The number of samples will be reduced drastically, from O(n^2) to worst case O(b*k*t) where b is the number of bins, k is the number of features, and t is the number of classes ( if it’s classification problem).
However, the binned samples’ density will be altered for sure. But if you care about the decision boundary more than the actual density, then this is surely helpful.
Now here comes the fancy thing: FeatureDiscretizer.
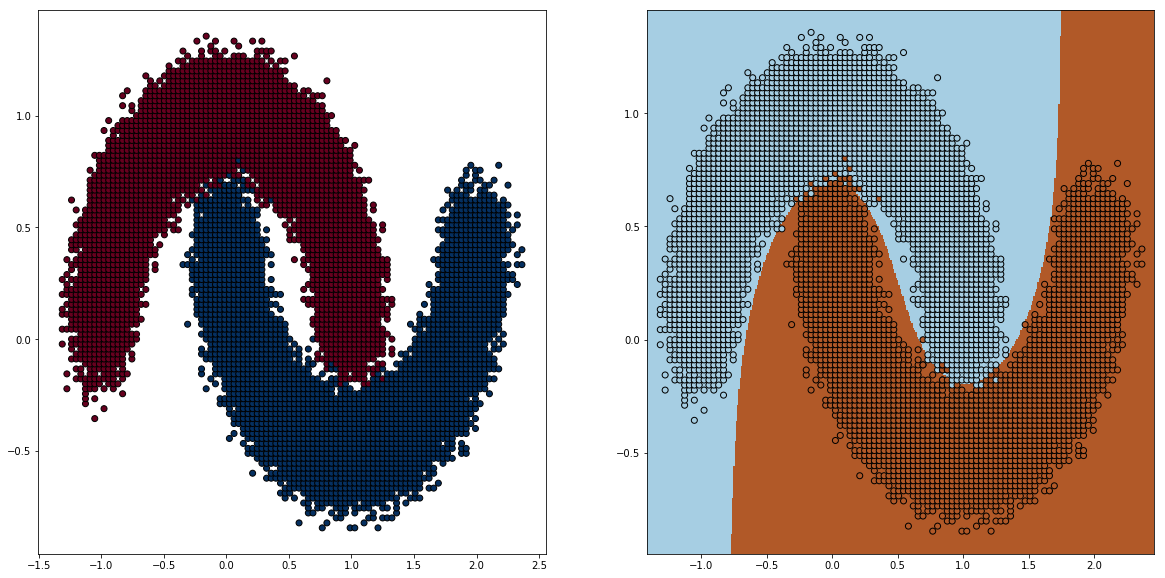
With 100 bins, the sample size reduced from 100k to roughly 5000, using KBinsDiscretizer from Sklearn.
There are several ways to obtain the bins; here I choose uniform (all buckets are the same size; you can also choose quantile, where all buckets have the same number of points). Notice how spread out the samples are.
Note that this method doesn’t work well out of the box with density-based methods like GaussianProcess etc. Density estimates from this method aren’t guaranteed to be correct. I bet there are weighting tricks to make it match :)
Check out the notebook here.